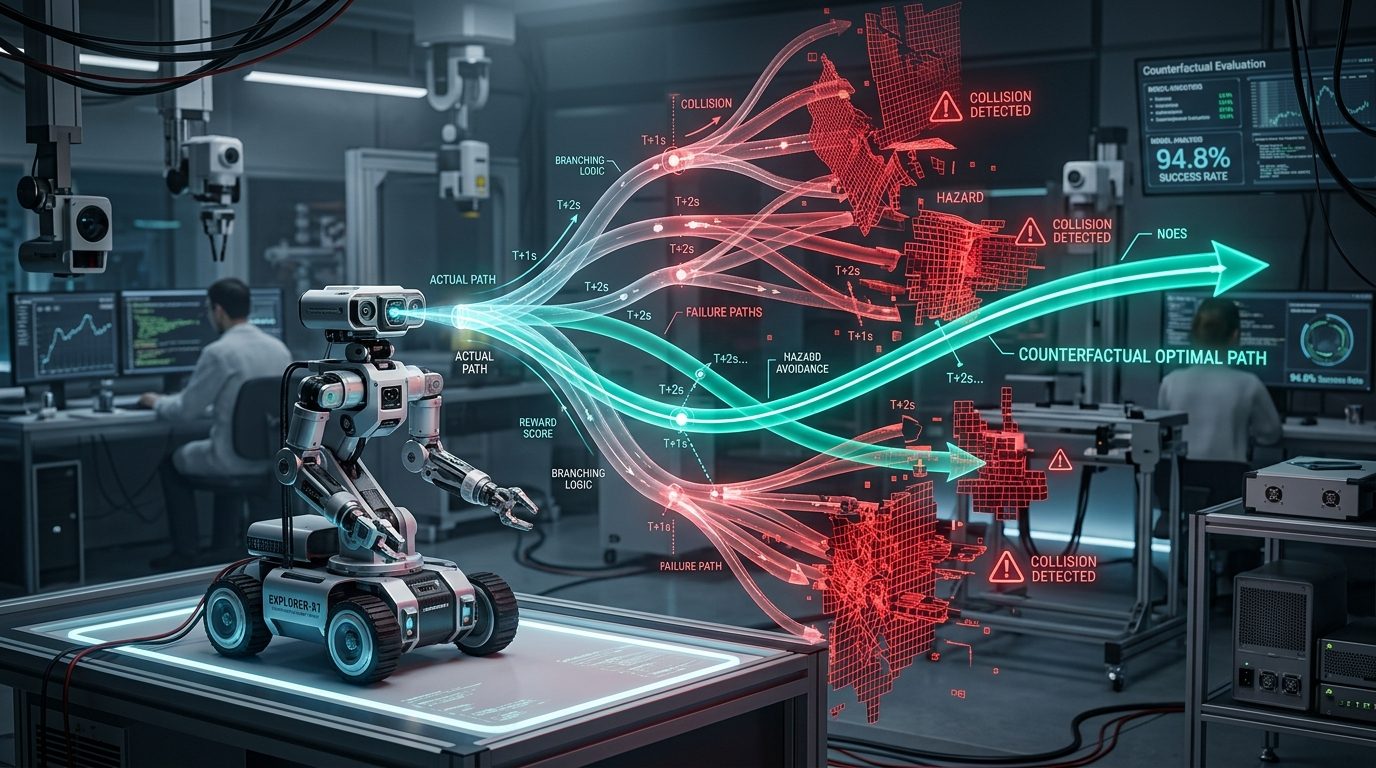
Autonomous artificial intelligence agents have long been plagued by an inability to foresee the consequences of their own actions. Once an agent issues a terminal command like `rm -rf /` or sends an unauthorized email to a corporate client, the mistake cannot be undone by adjusting attention weights.
On September 8, 2026, researchers published an architectural breakthrough titled 'Counterfactual Latent Simulation for Resilient Agentic Execution,' detailing how agents can construct internal world models to simulate reality before acting.
Inspired by human imagination and cognitive neuroscience, the framework integrates a dual-system cognitive architecture. When presented with a complex objective, System 1 proposes candidate action sequences. Instead of passing these directly to external APIs, System 2 routes them into a trained Latent World Model (LWM).
The world model constructs an internal sandbox representing the target environment's state—including file structures, server network connections, and third-party database constraints. It executes forward rollout simulations across dozens of branching trajectories, scoring each branch for goal alignment and latent failure risk.
If a simulated branch leads to an unintended error state (such as a server crash or data loss), the agent identifies the causal inflection point, prunes that action tree, and searches for alternative paths. In empirical benchmarks spanning autonomous DevOps and robotic manipulation, the counterfactual architecture eliminated over 80% of unforced execution errors, setting a new paradigm for trustworthy autonomous agency.