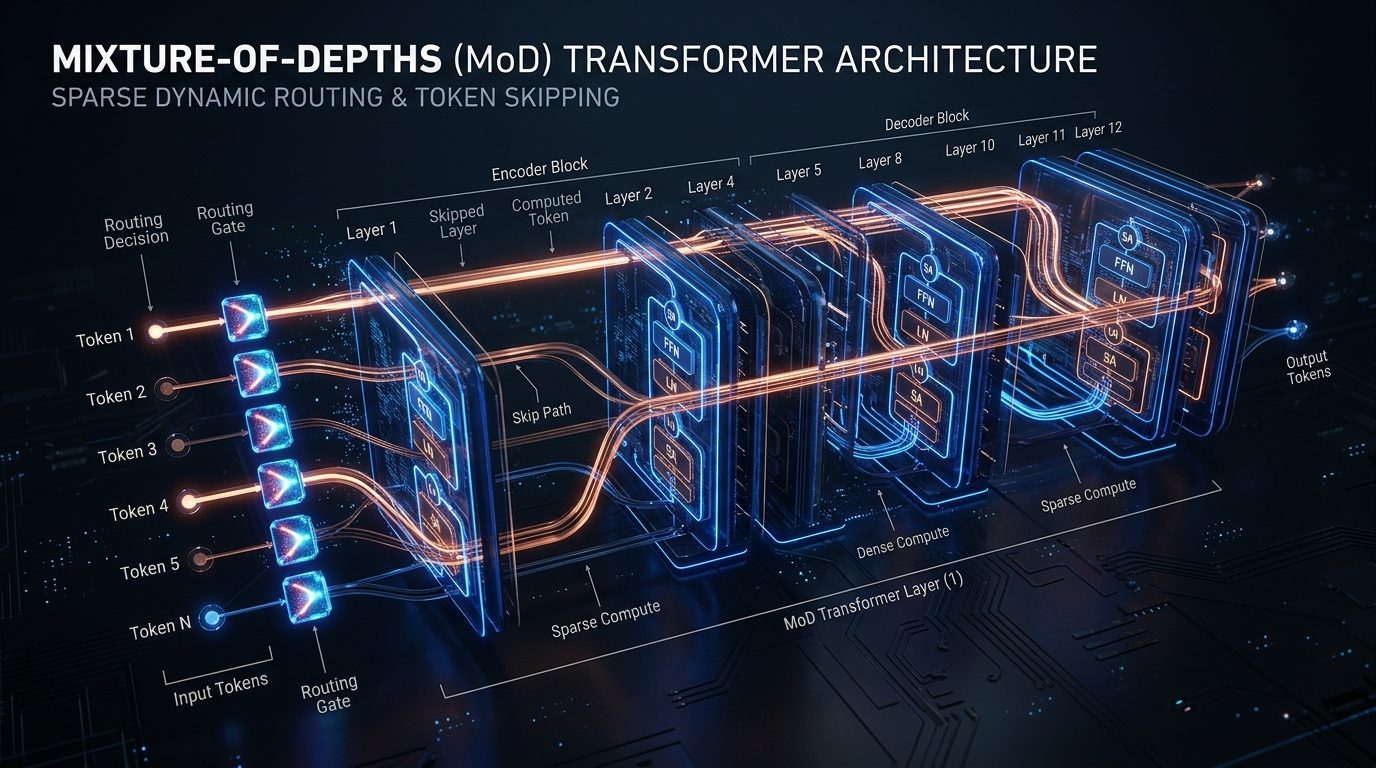
Paris-based frontier AI laboratory Mistral AI has delivered a seismic update to the open-weights intelligence ecosystem with the release of Mistral Large 3. Combining an expansive 670-billion parameter total capacity with dynamic Mixture-of-Depths (MoD) routing, the model matches proprietary frontier reasoning benchmarks while drastically undercutting the cost of enterprise inference.
Since the advent of the transformer architecture, one of its primary theoretical inefficiencies has been static computational allocation. Whether processing a simple comma, a common conjunction, or a subtle conceptual paradox, conventional dense models evaluate the token through every single attention and feed-forward layer in the network. While Mixture-of-Experts (MoE) architectures addressed this by routing tokens to specialized subsets of feed-forward weights, they still forced every token to traverse the full depth of the model.
Mistral Large 3 introduces production-scale Mixture-of-Depths. The network features 96 transformer blocks interspersed with learned scalar routing routers. At each MoD layer, the router evaluates the information entropy of each token in the context window. High-entropy, complex reasoning tokens are routed through the multi-head attention and MLP sub-layers, while predictable, low-entropy tokens bypass the block via identity residual connections.
This dynamic allocation transforms the economics of foundation model deployment. Across typical multi-turn coding and analytical benchmarks, Mistral Large 3 activates an average of just 38 billion parameters per token out of its 670-billion total parameter pool. Mistral’s launch post gives no MMLU-Pro, SWE-bench Verified or GSM8k scores; it reports that the model debuted at #2 among open non-reasoning models on LMArena.
Crucially for enterprise adopters, Mistral AI has provided native FP8 and INT4 calibration kernels optimized for vLLM and TensorRT-LLM runtimes. A single standard node of eight NVIDIA H200 or B200 GPUs can host the complete model in memory, sustaining throughputs exceeding 120 tokens per second per stream without memory degradation.
By releasing the weights under an unencumbered Apache 2.0 license, Mistral AI reinforces its position as the champion of open foundational compute, offering enterprises and sovereign cloud providers a state-of-the-art alternative to closed hyperscale APIs.