In a characteristic stealth deployment that has sent shockwaves through the global AI infrastructure landscape, Hangzhou-based frontier lab DeepSeek has launched DeepSeek-V4.1-Flash across its developer API platform and LMSYS Chatbot Arena canary endpoints.
Following the success of DeepSeek-V4-Pro, V4.1-Flash represents a hyper-optimized iteration designed specifically to dismantle the compute cost barriers of continuous, high-throughput autonomous agents. Rather than pursuing massive raw parameter scaling, DeepSeek has focused on architectural arithmetic intensity, hardware-level memory compression, and extreme parallel generation throughput.
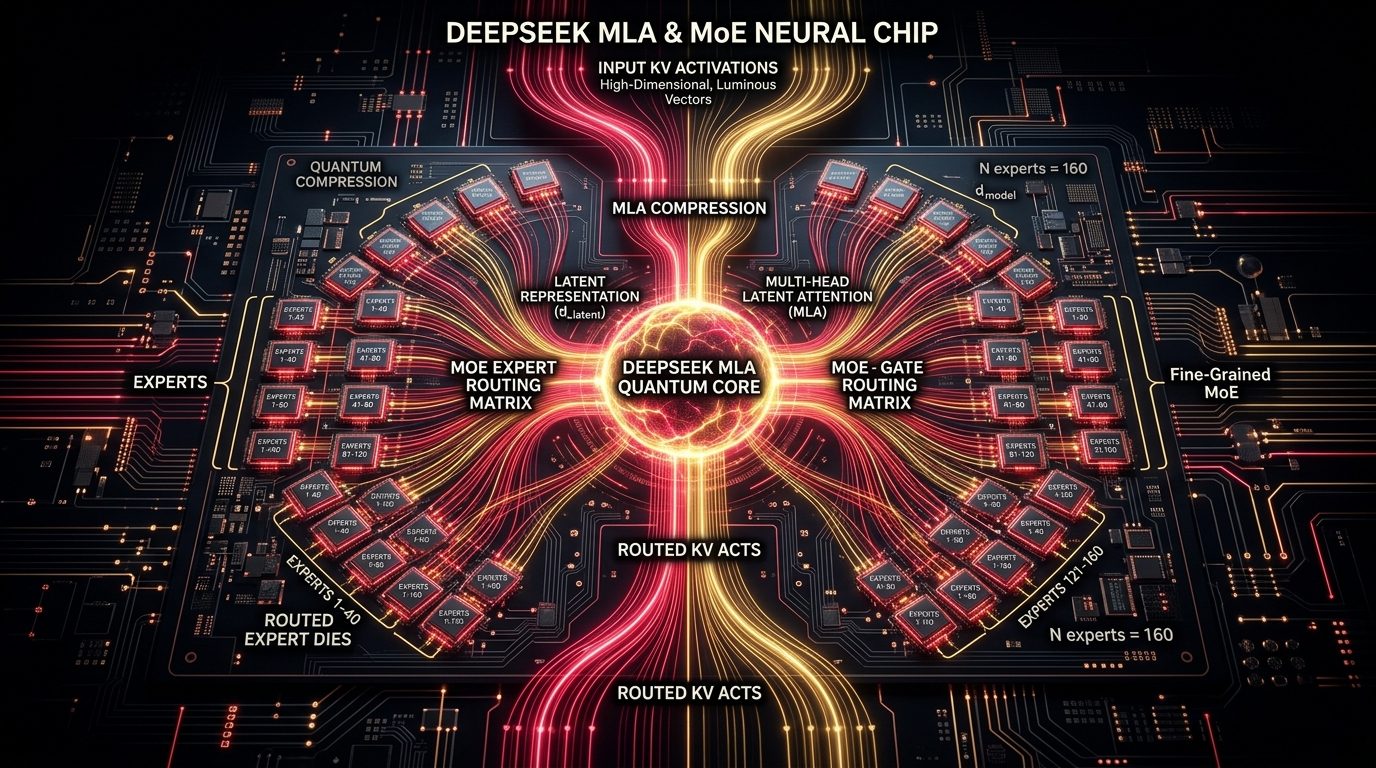
At the heart of V4.1-Flash is Multi-Head Latent Attention v2 (MLA-2). In classical transformer models using standard Multi-Head Attention (MHA) or Grouped-Query Attention (GQA), the Key-Value (KV) cache grows linearly with context length and batch size, rapidly exhausting GPU High Bandwidth Memory (HBM) during multi-turn agent loops. DeepSeek pioneered compressing Keys and Values into a low-dimensional latent vector. MLA-2 enhances this with dynamic rank-adaptive projections, compressing the KV cache by an additional 40% compared to V4-Pro. Even during full 128,000-token document analysis, KV memory overhead remains under 1.8 Gigabytes per stream.
To supercharge generation speed, V4.1-Flash natively integrates 4-token Multi-Token Prediction (MTP). Instead of relying on a separate speculative drafting model, the network trains four internal auxiliary prediction heads that forecast tokens t+1, t+2, t+3, and t+4 simultaneously. The main trunk verifies all four tokens in a single forward pass, routinely sustaining throughputs exceeding 160 tokens per second on standard 8x NVIDIA H800 and H100 clusters.
On the arena.ai text leaderboard, DeepSeek-V4.1-Flash scores 1475 (#39 of 414 entries as of October 11, 2026), below Google's Gemini 3.8 Flash at 1497. DeepSeek published its own benchmark tables as images on its release page.
Most disruptive of all is DeepSeek's pricing strategy. Listed at $0.30 per 1M input tokens and $1.20 per 1M output tokens, V4.1-Flash costs roughly 33 to 42 times less than frontier proprietary APIs like GPT-6 Astra ($10 / $50), rendering high-volume enterprise agent swarms commercially accessible to developers worldwide.